Açıklama
Bring AI NPCs, digital companions, and story characters to life with emotion, lip sync, and expressive facial performance in one Unreal Engine plugin.
Add simple emotion tags to dialogue such as [Happy4], [Thinking2], or [Surprise5]. FaceEmote strips the tags before speech, syncs each emotional change to the spoken word via TTS timestamps, and blends expression with lip sync so characters react naturally, even mid-sentence.
For AI characters, FaceEmote includes OpenAI-compatible LLM nodes plus native Inworld and ElevenLabs TTS in Blueprint, from generated dialogue to a voiced, emoting character with no separate plugins.
Key Features
AI Dialogue → Facial Performance: LLM Chat and Prompt nodes plus async streaming TTS. Put the emotion-tag instructions in your system prompt and the model's reply flows straight into speech and performance — the LLM scores it, FaceEmote plays it.
Tag-Driven Emotion: Place emotional direction anywhere in dialogue: `[Thinking2] I thought I understood... [Surprise4] wait, WHAT?`
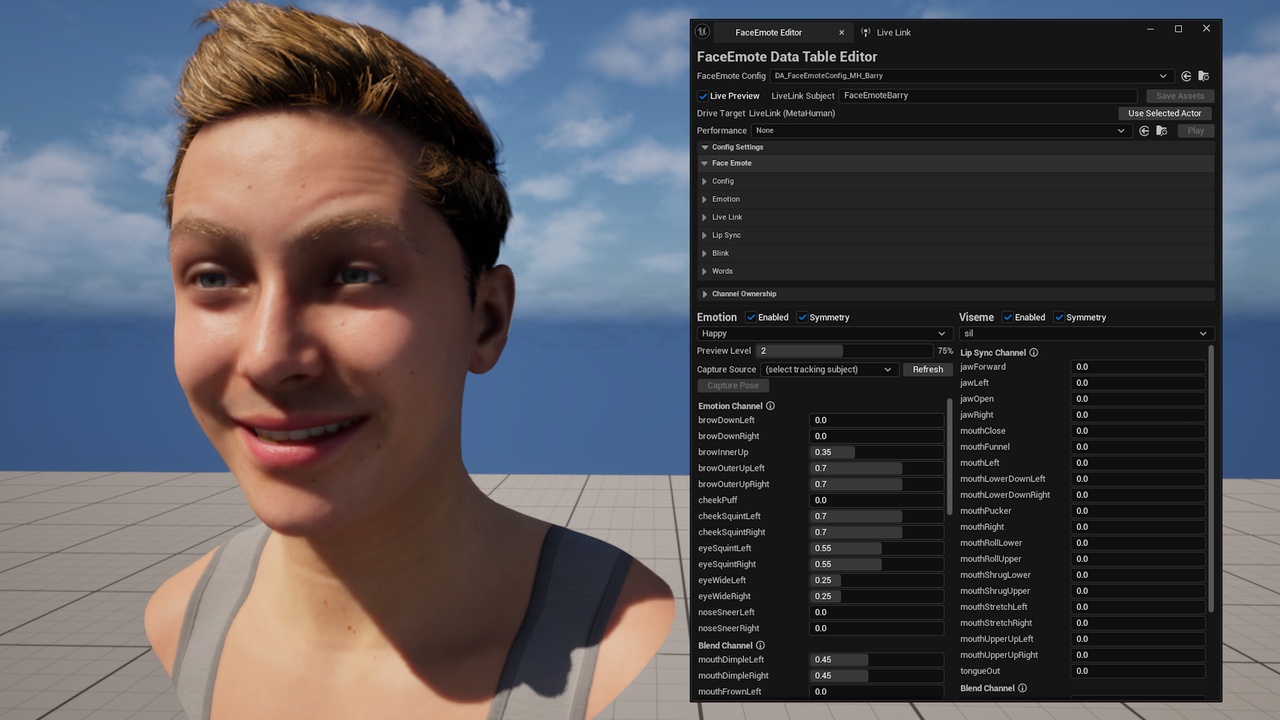
Authorable Emotion System: 9 emotion families × 5 intensity tiers (45 expressions) + Neutral, in both ARKit and MetaHuman data tables. Create your own emotions, poses, and intensity per character.
Emotion + Lip Sync Without Fighting: The Channel Ownership system decides, per facial shape, who owns it while silent vs. speaking, emotion, lip sync, eye tracking, or partial expression. Characters smile, frown, and react while still speaking clearly.
Built-In Lip Sync: Self-contained English text-driven lip sync, a CMU-dictionary phonemizer (~134k words) feeding 15 visemes with co-articulation. No external solution required.
Bring-Your-Own Lip Sync: Release the mouth to any audio-analysis solution, including the free FaceEmoteOVR bridge for Meta's OVRLipSync, or feed any analyzer's per-frame visemes through the provider-agnostic viseme input.
Organic Motion: Optional eased/spring transitions with regional stagger, per-shape timing jitter, through-neutral blending, drift-and-hold micro-motion, micro-expression fidgets, procedural blinking, and emotion-change blinks, so idle faces breathe and transitions read as intention, not interpolation.
Spoken-Word Highlighting: Per-word rich-text events, clean, or with emotion tags styled inline, for subtitles and karaoke-style dialogue UI, live and on replays.
FaceEmote Editor: Author emotions, visemes, and channel ownership live on your character with no Play session, slider-edit rows by channel, tune co-articulation, save tables to disk. Capture expressions from a webcam or iPhone/Live Link Face straight into an emotion pose.
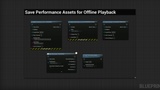
Reusable Performances: Bake audio, emotion timing, visemes, and word timing into replayable Performance assets, in the editor or at runtime in shipping builds. Generate once, replay free.
MetaHuman, ARKit & Custom Rigs: Drive MetaHumans through Live Link (one subject per character, any number of characters) or control ARKit/custom morph-target characters directly. Automatic ARKit→MetaHuman remapping means the same authored data works on both.
Built for Two Workflows
Live AI Characters: Generate dialogue through FaceEmote's LLM nodes or supply tagged text from any source. Non-blocking HTTP streams TTS audio as it's synthesized; a self-calibrating playback clock keeps emotion timing, lip sync, and word events locked to the audio across many characters at once.
Authored Production: Write tagged dialogue yourself, preview and refine it in the editor, then save it for deterministic replay in cinematics, quests, conversations, and tutorials. Zero TTS calls at runtime.
LLM & TTS Details
Any OpenAI-compatible endpoint: OpenAI, OpenRouter, Groq, DeepSeek, Mistral, Together, Fireworks, xAI, or a local server (Ollama, LM Studio). Set the Base URL and go.
Full request control: System prompt, temperature, max tokens, stop sequences, timeout, and a JSON escape hatch for provider-specific options. Responses return finish reason, token usage, and raw JSON.
Streaming TTS with word timing: Inworld and ElevenLabs chunks play the moment they arrive, each carrying the word-level timestamps that drive emotion beats, visemes, and highlighting.
Credentials out of your Blueprints: API keys resolve from Project Settings, then environment variables, then an optional per-call override.
Pre-Recorded or Multilingual Audio
FaceEmote's built-in lip sync is English and text-driven. For everything else:
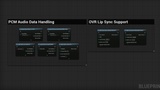
Audio Import Toolkit (included): Decode WAV, MP3, FLAC, OGG Vorbis, OGG Opus, and Bink to PCM at runtime, from files, memory, or SoundWave assets, plus WAV export. No importer plugin needed.
FaceEmoteOVR bridge (free add-on): Waveform-driven OVRLipSync for recorded audio, SoundWave assets, streamed PCM, and TTS output in any language, with FaceEmote's emotions, organic motion, and Channel Ownership still active on top.
Built-in text-driven lip sync is English only; other languages need FaceEmoteOVR or another audio analyzer.
Automatic emotion-tag timing requires TTS word timestamps; pre-recorded audio uses hand-placed emotions.
LLM nodes return complete responses (TTS streams; LLM token streaming is not yet supported).
Inworld, ElevenLabs, and hosted LLM providers require your own API credentials and may have separate usage costs.
Technical Details
Engine: Unreal Engine 5.7 (5.8 support coming soon)
Rig Support: MetaHuman (Live Link), ARKit-standard morph targets, custom blend-shape characters.
TTS: Inworld + ElevenLabs (async streaming, word timestamps).
LLM: OpenAI-compatible Chat / Prompt nodes, any endpoint including local LLM’s.
Lip Sync: Built-in 15-viseme English system + external viseme input + free OVRLipSync bridge.
Audio Import: WAV, MP3, FLAC, OGG Vorbis, OGG Opus, Bink → PCM; WAV export
Modules: FaceEmote Runtime + FaceEmoteEditor
Access: 100% Blueprint runtime API + well-commented C++ source included.
Platform Support: Windows
Included
Runtime + Editor modules with Full C++ source.
45-expression emotion library + Neutral (ARKit and MetaHuman tables)
9 starter emotions + Neutral.
Config and Channel Ownership presets for both rigs.
MetaHuman and ARKit example characters, demo room and test map.
Example Performance assets and Blueprint integration examples.
Documentation and integration guide, talking and emoting in under 30 minutes.
Documentation: LINK
Packaged Demo - Windows: LINK
Discord Support: COMING SOON
Technical Support: [email protected]
Website: https://meddlingkids.net